AI Training Dataset Market
AI Training Dataset Market Size, Scope, Growth, Trends and By Segmentation Types, Applications, Regional Analysis and Industry Forecast (2026-2034)
Report ID : RI_711111 | Published On : October 08, 2026 |
Format : 


 | Author : Vigneshwaran Mahadik
AI Training Dataset Market Size
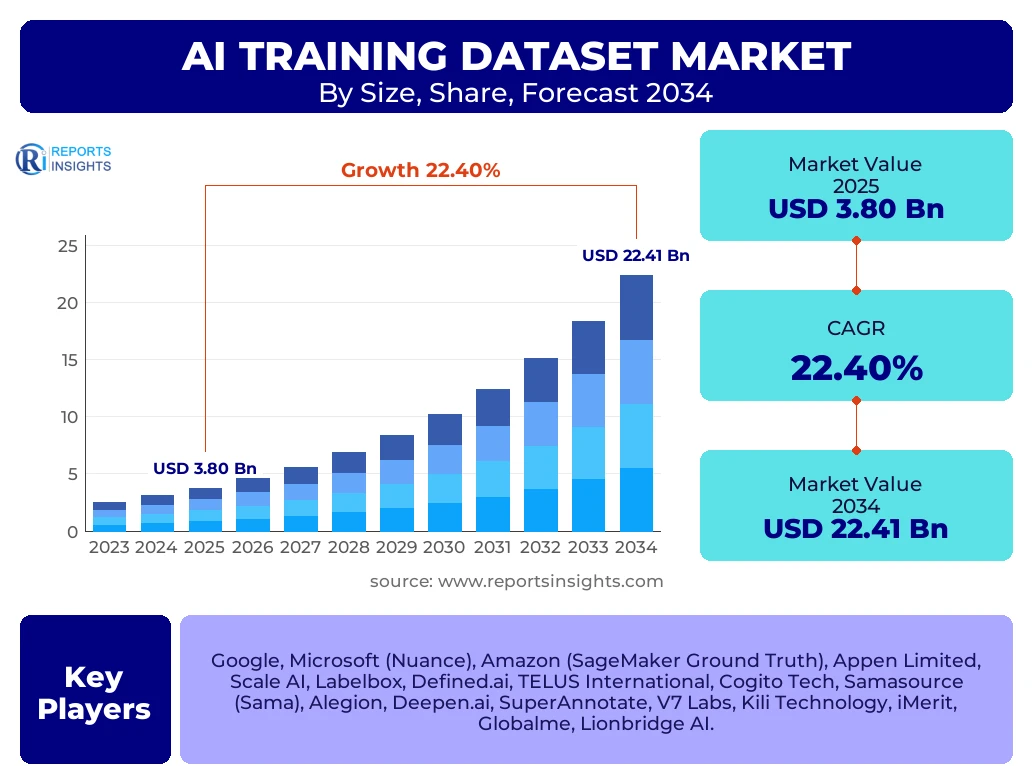
According to Reports Insights Consulting Pvt Ltd, The AI Training Dataset Market is projected to grow at a Compound Annual Growth Rate (CAGR) of 22.4% between 2025 and 2034. The market is estimated at USD 4.65 Billion in 2026 and is projected to reach USD 22.41 Billion by the end of the forecast period in 2034.
The global AI Training Dataset market is currently experiencing a transformative phase, driven by the exponential rise of Generative AI (GenAI) and Large Language Models (LLMs). As enterprises transition from experimental AI pilots to full-scale production, the demand for high-quality, diverse, and ethically sourced data has become the primary bottleneck for innovation. The market's expansion is not merely quantitative but qualitative, with a significant shift toward specialized, domain-specific datasets in sectors such as healthcare, legal, and finance.
Furthermore, the integration of Human-in-the-Loop (HITL) methodologies remains a critical component of the market ecosystem. While automated labeling tools have improved efficiency, the requirement for human-verified data to eliminate algorithmic bias and ensure factual accuracy in RLFH (Reinforcement Learning from Human Feedback) remains a key value driver. This synergy between automated preprocessing and human expert validation is defining the current competitive landscape of the market.
Key AI Training Dataset Market Trends & Insights
The AI Training Dataset market is evolving beyond simple data collection toward sophisticated data curation and synthetic generation. As traditional data sources become exhausted or restricted by privacy laws, organizations are increasingly turning to synthetic data to fill gaps in training sets, particularly for edge cases in autonomous driving and medical imaging. This trend is coupled with a rising demand for multimodal datasets that allow AI models to process and correlate information across text, image, and video formats simultaneously, reflecting the industrys move toward more holistic artificial intelligence.
- North America currently stands as the largest region by market share, accounting for over 35% of the global valuation due to the presence of major tech conglomerates and AI research hubs.
- The Asia-Pacific region is identified as the fastest-growing market, projected to expand at a CAGR exceeding 24% as digital transformation accelerates in China, India, and Southeast Asia.
- The Text dataset segment remains the largest in terms of market share, driven by the global surge in LLM development and conversational AI applications.
- The Healthcare vertical is emerging as a high-growth segment, utilizing specialized image and video datasets for diagnostic AI and robotic surgery training.
- Increasing adoption of "Data-centric AI" approaches, where the focus shifts from tweaking algorithms to improving the quality and consistency of the underlying datasets.
Key Takeaways AI Training Dataset Market Size & Forecast
The market forecast indicates a robust upward trajectory as AI moves from a niche technological advantage to a foundational enterprise requirement. Key stakeholders are prioritizing data sovereignty and security, leading to a rise in localized data collection and processing. The market is also seeing a consolidation of players, where smaller labeling startups are being acquired by larger cloud service providers to offer end-to-end AI development pipelines.
- The United States is the leading country contributor to the market, fueled by massive investments from private equity and venture capital into AI startups.
- Synthetic data generation is expected to experience the highest growth rate among data collection methods, providing a solution to privacy concerns and data scarcity.
- Enterprise adoption of custom AI models is driving the demand for proprietary and licensed datasets over public-domain data.
- Quality over quantity has become the primary mantra, with high-fidelity, meticulously annotated datasets commanding significant price premiums.
- Government initiatives and subsidies in regions like Europe and the Middle East are fostering local AI ecosystems, further decentralizing market growth.
AI Training Dataset Market Drivers Analysis
The primary driver for the AI Training Dataset market is the relentless expansion of Generative AI across diverse business functions. Organizations are requiring massive amounts of data to fine-tune pre-trained models for specific industry use cases. Additionally, the proliferation of Internet of Things (IoT) devices and the digitalization of historical records provide a vast repository of raw information that requires structured labeling and cleaning for AI consumption.
| Drivers | (~) Impact on CAGR % Forecast | Regional/Country Relevance | Impact Time Period |
|---|---|---|---|
| Surge in Generative AI and LLM Development | +5.5% | Global | 2025 - 2034 |
| Advancements in Autonomous Vehicle Sensors | +3.8% | USA, Germany, China | 2026 - 2030 |
| Digitization of Healthcare Records and Medical Imaging | +4.2% | Europe, North America | 2025 - 2034 |
| Expansion of E-commerce and Personalized Marketing | +3.1% | India, Brazil, Southeast Asia | 2025 - 2029 |
AI Training Dataset Market Restraints Analysis
Market growth is significantly challenged by stringent data privacy regulations such as GDPR in Europe and various state-level acts in the US. These regulations limit the use of personal data without explicit consent, increasing the complexity and cost of data acquisition. Furthermore, the high cost associated with expert-level manual annotation for specialized fields like law and medicine prevents many small-to-medium enterprises from building robust AI models.
| Restraints | (~) Impact on CAGR % Forecast | Regional/Country Relevance | Impact Time Period |
|---|---|---|---|
| Strict Data Privacy and Compliance Regulations | -2.8% | European Union, USA | 2025 - 2034 |
| High Cost of Expert Human Annotation | -2.1% | Global | 2025 - 2030 |
| Data Security Concerns in Cloud Environments | -1.5% | Middle East, APAC | 2026 - 2034 |
AI Training Dataset Market Opportunities Analysis
The rise of synthetic data represents the single largest opportunity in the market, allowing for the creation of perfectly labeled data at a fraction of the cost of manual labeling. Additionally, there is a burgeoning market for ethical and "fair" datasets that are pre-scrubbed of biases, catering to companies that prioritize Responsible AI. The emergence of Edge AI also opens opportunities for localized dataset generation that respects user privacy while improving model latency.
| Opportunities | (~) Impact on CAGR % Forecast | Regional/Country Relevance | Impact Time Period |
|---|---|---|---|
| Development of Synthetic Data Generation Platforms | +4.8% | USA, Israel, United Kingdom | 2025 - 2034 |
| Rise of Niche/Vertical Specific Datasets | +3.5% | Global | 2026 - 2032 |
| Demand for Bias-Free and Ethical AI Datasets | +2.9% | Europe, North America | 2025 - 2034 |
AI Training Dataset Market Challenges Impact Analysis
Maintaining data consistency and quality at scale remains a daunting challenge for the industry. As datasets grow into the petabyte range, ensuring that labeling remains uniform across thousands of annotators is difficult. Additionally, the risk of "Model Collapse"—where AI models trained on AI-generated data begin to lose accuracy—poses a significant technical challenge for the long-term sustainability of synthetic data ecosystems.
| Challenges | (~) Impact on CAGR % Forecast | Regional/Country Relevance | Impact Time Period |
|---|---|---|---|
| Maintaining Consistency in Large-Scale Annotation | -1.9% | Global | 2025 - 2028 |
| Risk of Model Collapse from Synthetic Data | -2.4% | Global | 2027 - 2034 |
| Intellectual Property and Copyright Issues | -3.0% | USA, EU | 2025 - 2034 |
AI Training Dataset Market - Updated Report Scope
The scope of this report covers the end-to-end ecosystem of AI training data, ranging from raw data collection and cleaning to advanced annotation and synthetic data generation. It provides a granular analysis of market dynamics across various data types and industry verticals, ensuring stakeholders have a comprehensive view of the competitive landscape and technological shifts.
| Report Attributes | Report Details |
|---|---|
| Base Year | 2025 |
| Historical Year | 2020 to 2024 |
| Forecast Year | 2026 - 2034 |
| Market Size in 2025 | USD 3.80 Billion |
| Market Forecast in 2034 | USD 22.41 Billion |
| Growth Rate | 22.4% CAGR |
| Number of Pages | 245 |
| Key Trends |
|
| Segments Covered |
|
| Key Companies Covered | Google, Microsoft (Nuance), Amazon (SageMaker Ground Truth), Appen Limited, Scale AI, Labelbox, Defined.ai, TELUS International, Cogito Tech, Samasource (Sama), Alegion, Deepen.ai, SuperAnnotate, V7 Labs, Kili Technology, iMerit, Globalme, Lionbridge AI. |
| Regions Covered | North America, Europe, Asia Pacific (APAC), Latin America, Middle East, and Africa (MEA) |
| Speak to Analyst | Avail customised purchase options to meet your exact research needs. Request For Analyst Or Customization |
Segmentation Analysis
The AI Training Dataset market is segmented primarily by data type and industry application, with the text segment currently dominating due to the prevalence of Natural Language Processing (NLP) technologies. However, the video segment is witnessing the most rapid growth as advancements in computer vision for security, retail analytics, and autonomous systems necessitate high-frame-rate, accurately labeled video data. Industry-wise, the automotive sector remains a heavy consumer of datasets for ADAS development, while the healthcare sector is increasingly investing in high-fidelity imaging data for AI-assisted diagnostics.
- By Data Type:
- Text (Sentiment analysis, entity recognition, translation)
- Image (Object detection, semantic segmentation, facial recognition)
- Audio (Speech-to-text, speaker identification, acoustic modeling)
- Video (Action recognition, temporal annotation, motion tracking)
- By Vertical:
- IT & Telecommunications (Chatbots, network optimization)
- Automotive (Autonomous driving, in-cabin monitoring)
- Healthcare (Medical imaging, drug discovery)
- Retail & E-commerce (Product recommendations, visual search)
- BFSI (Fraud detection, algorithmic trading)
- Government & Defense (Surveillance, geospatial analysis)
- By Collection Method:
- Internal Data Sourcing
- Crowdsourcing Platforms
- Synthetic Data Generation
- Third-party Dataset Licensing
Regional Highlights
- North America: The largest market share holder, North America is home to the world’s leading AI researchers and technology firms. The region benefits from a robust venture capital ecosystem and an early-adopter culture in the enterprise sector. The US specifically leads in the development of foundational models, necessitating vast quantities of diverse training data.
- Asia-Pacific: The fastest-growing region, driven by massive investments in AI infrastructure in China and India. The region’s large population provides a vast base for data collection, particularly in mobile-first applications and smart city initiatives. Government-led AI strategies in these nations are providing a significant tailwind for local dataset providers.
- Europe: A region characterized by a strong focus on ethical AI and data privacy. The European market is a leader in the development of synthetic data technologies as a response to strict GDPR compliance requirements. Germany and the UK are the primary hubs for automotive and financial AI datasets.
- LAMEA: While currently smaller in market share, the Middle East is rapidly investing in AI as part of national diversification strategies (e.g., Saudi Vision 2030). Africa is emerging as a significant hub for data labeling and crowdsourcing, providing employment while supporting global AI supply chains.

Top Key Players
The market research report includes a detailed profile of leading top wise companies in the AI Training Dataset Market.- Google LLC
- Microsoft Corporation
- Amazon Web Services (AWS)
- Appen Limited
- Scale AI
- Labelbox, Inc.
- Defined.ai
- TELUS International (formerly Lionbridge AI)
- Cogito Tech LLC
- Sama (formerly Samasource)
- Alegion
- Deepen.ai
- SuperAnnotate
- V7 Labs
- Kili Technology
- iMerit Technology Services
- Globalme (an Iyuno company)
- CloudFactory
- Playment (Acquired by TELUS International)
- TrainingData.io
Frequently Asked Questions
What is the current market size of the AI Training Dataset Market?
The market is estimated at USD 3.80 Billion in 2025 and is projected to reach USD 22.41 Billion by 2034, growing at a CAGR of 22.4%.
Which region is expected to grow the fastest during the forecast period?
The Asia-Pacific (APAC) region is expected to be the fastest-growing market, with a CAGR exceeding 24%, driven by rapid digital transformation and government support in China and India.
What are the primary drivers for the AI Training Dataset market?
Key drivers include the surge in Generative AI development, the advancement of autonomous vehicle technology, and the massive digitization of records across healthcare and financial sectors.
How is synthetic data impacting the market?
Synthetic data is providing a cost-effective and privacy-compliant alternative to manual data collection, helping to train models where real-world data is scarce or sensitive.
Who are the leading players in the AI Training Dataset market?
Leading players include global tech giants like Google and Amazon, alongside specialized data platforms such as Scale AI, Appen, Labelbox, and TELUS International.
Author
V
Vigneshwaran Mahadik is a Senior Analyst IT and Telecommunications Research with over 6+ years of experience in the IT and Telecommunications Industry. He specializes in technology market intelligence, digital transformation analysis, cloud computing trends, telecom infrastructure assessment, competitive benchmarking, market sizing, demand forecasting, and emerging technology evaluation across enterprise and communication ecosystems. His research combines comprehensive industry analysis with data-driven methodologies to help organizations make strategic business decisions, identify new growth opportunities, optimize operational strategies, anticipate evolving market trends, and strengthen their competitive positioning in the global IT and telecommunications landscape.
| Single User | : $3680 |
|---|---|
| Multi User | : $5680 |
| Corporate User | : $6400 |
Buy Now
Secure SSL Encrypted
